Modeller
Görsel, video, metin ve ses üreten 1142 model. Ara, filtrele, hemen dene.
 Text to Image
Sana Sprint
Sana Sprint is a text-to-image model capable of generating 4K images with exceptional speed.
 Text to Image
Sana v1.5 1.6B
Sana v1.5 1.6B is a lightweight text-to-image model that delivers 4K image generation with impressive efficiency.
 Text to Image
Sana v1.5 4.8B
Sana v1.5 4.8B is a powerful text-to-image model that generates ultra-high quality 4K images with remarkable detail.
 Video to Video
Scail 2
SCAIL-2 is an end-to-end character animation model that drives a reference character from a source video without relying on intermediate pose representations like skeleton maps.
 Text to Speech
Scribe V2
Transcribe speech with ElevenLabs Scribe v2. 90+ languages, word-level timestamps, speaker diarization for up to 32 speakers, audio event tagging, and keyterm biasing. Files up to 3 GB and 10 hours.
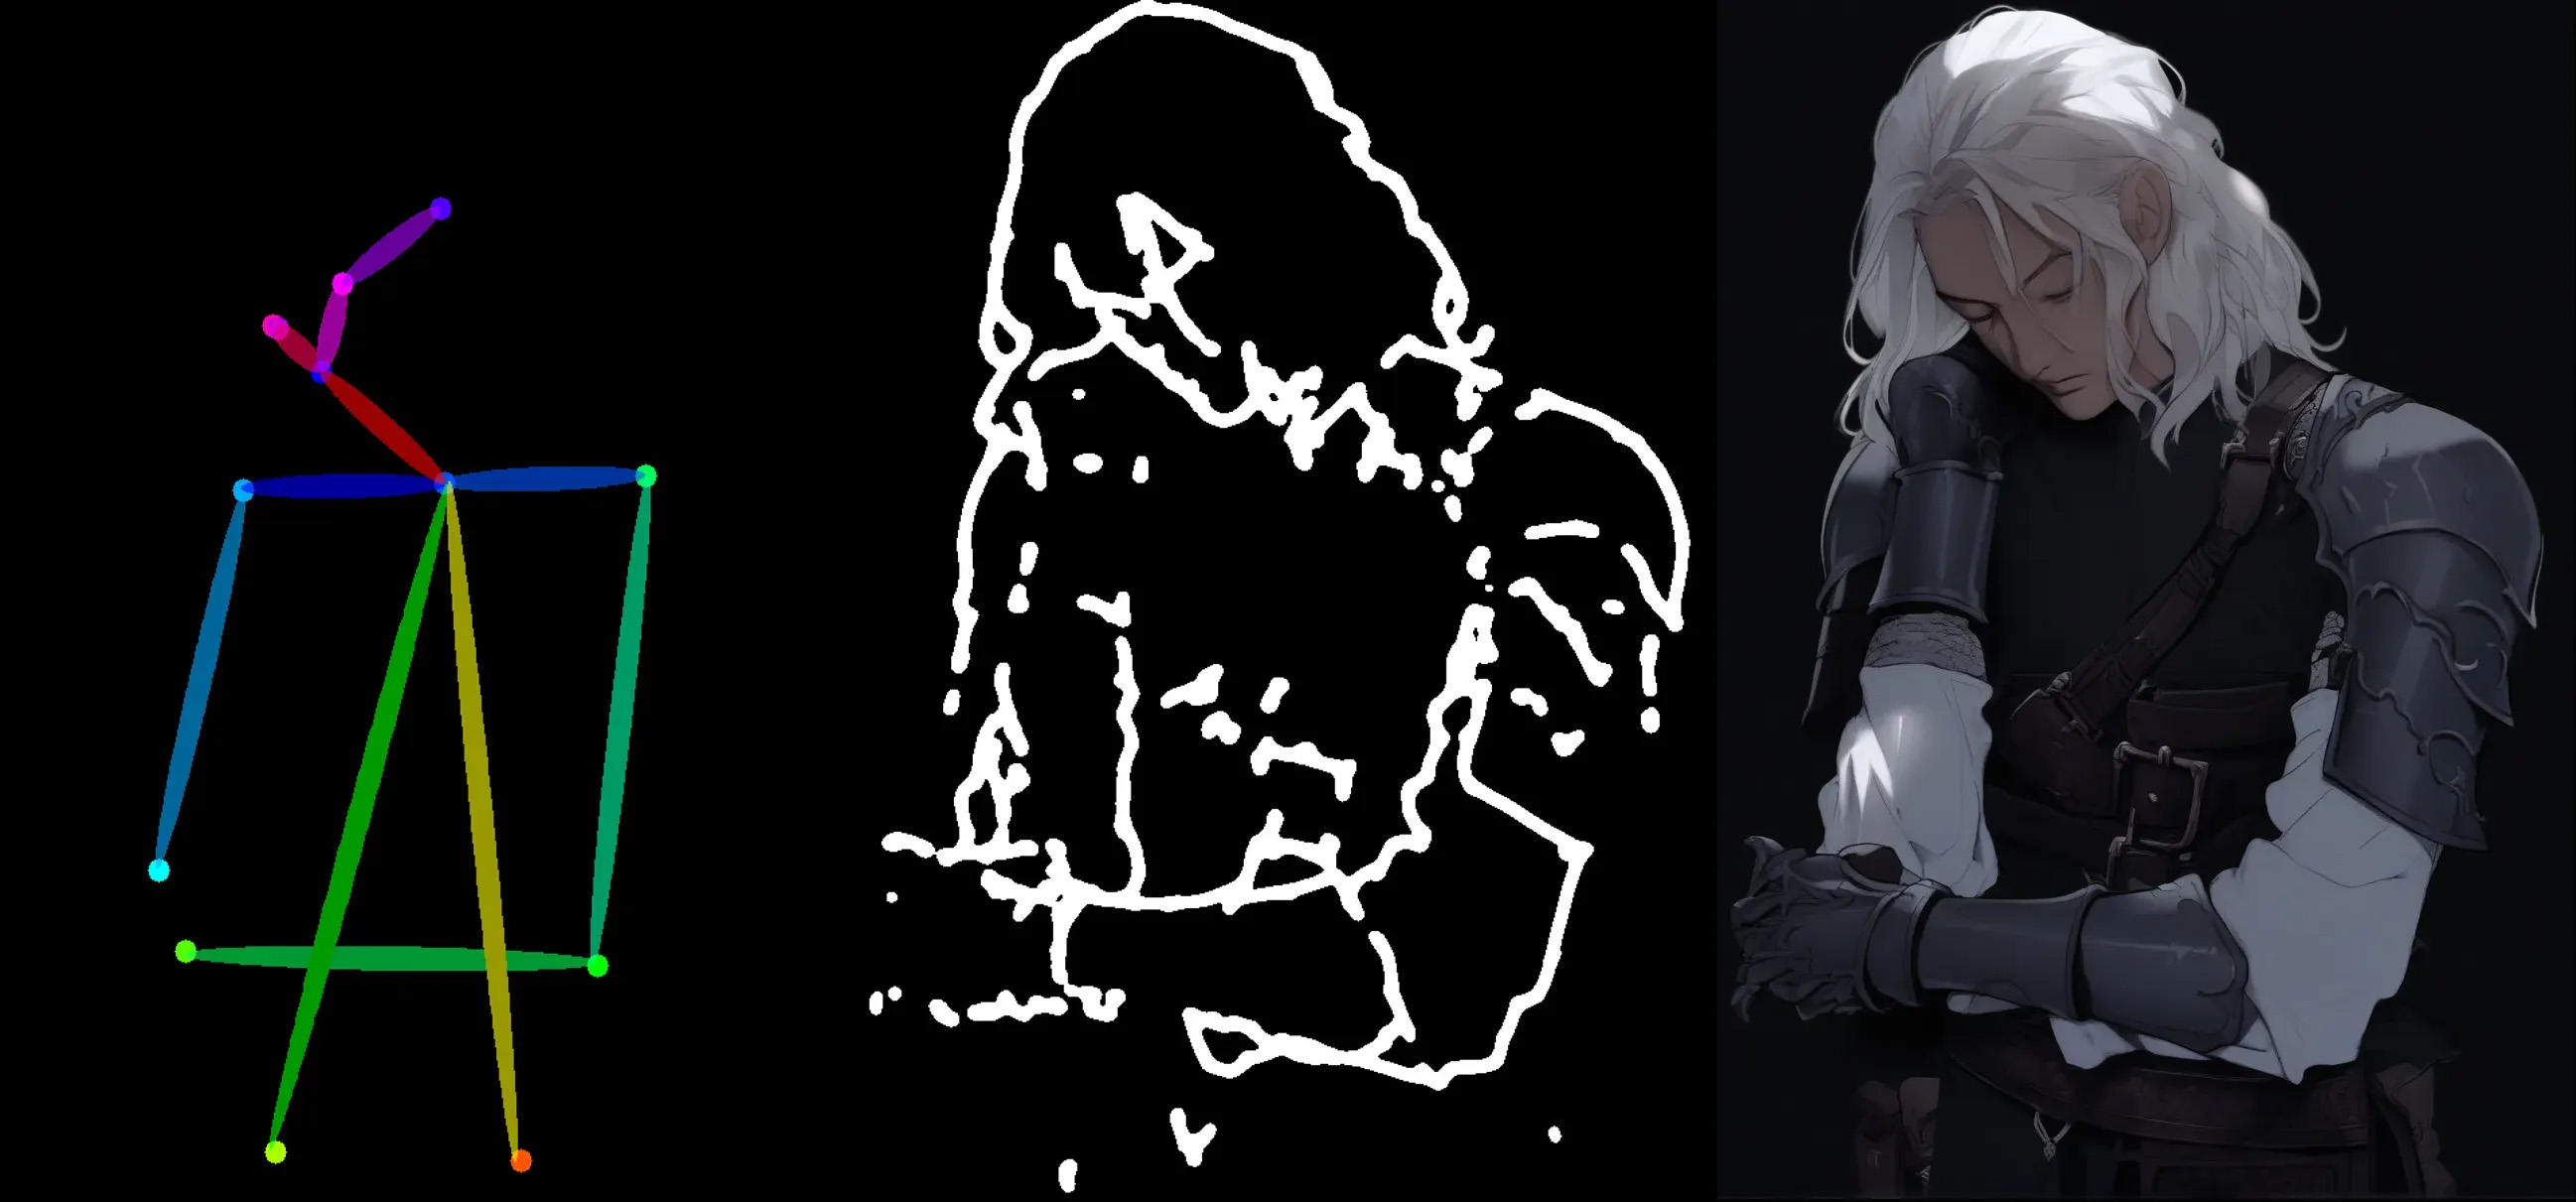 Image to Image
SDXL ControlNet Union
An efficent SDXL multi-controlnet text-to-image model.
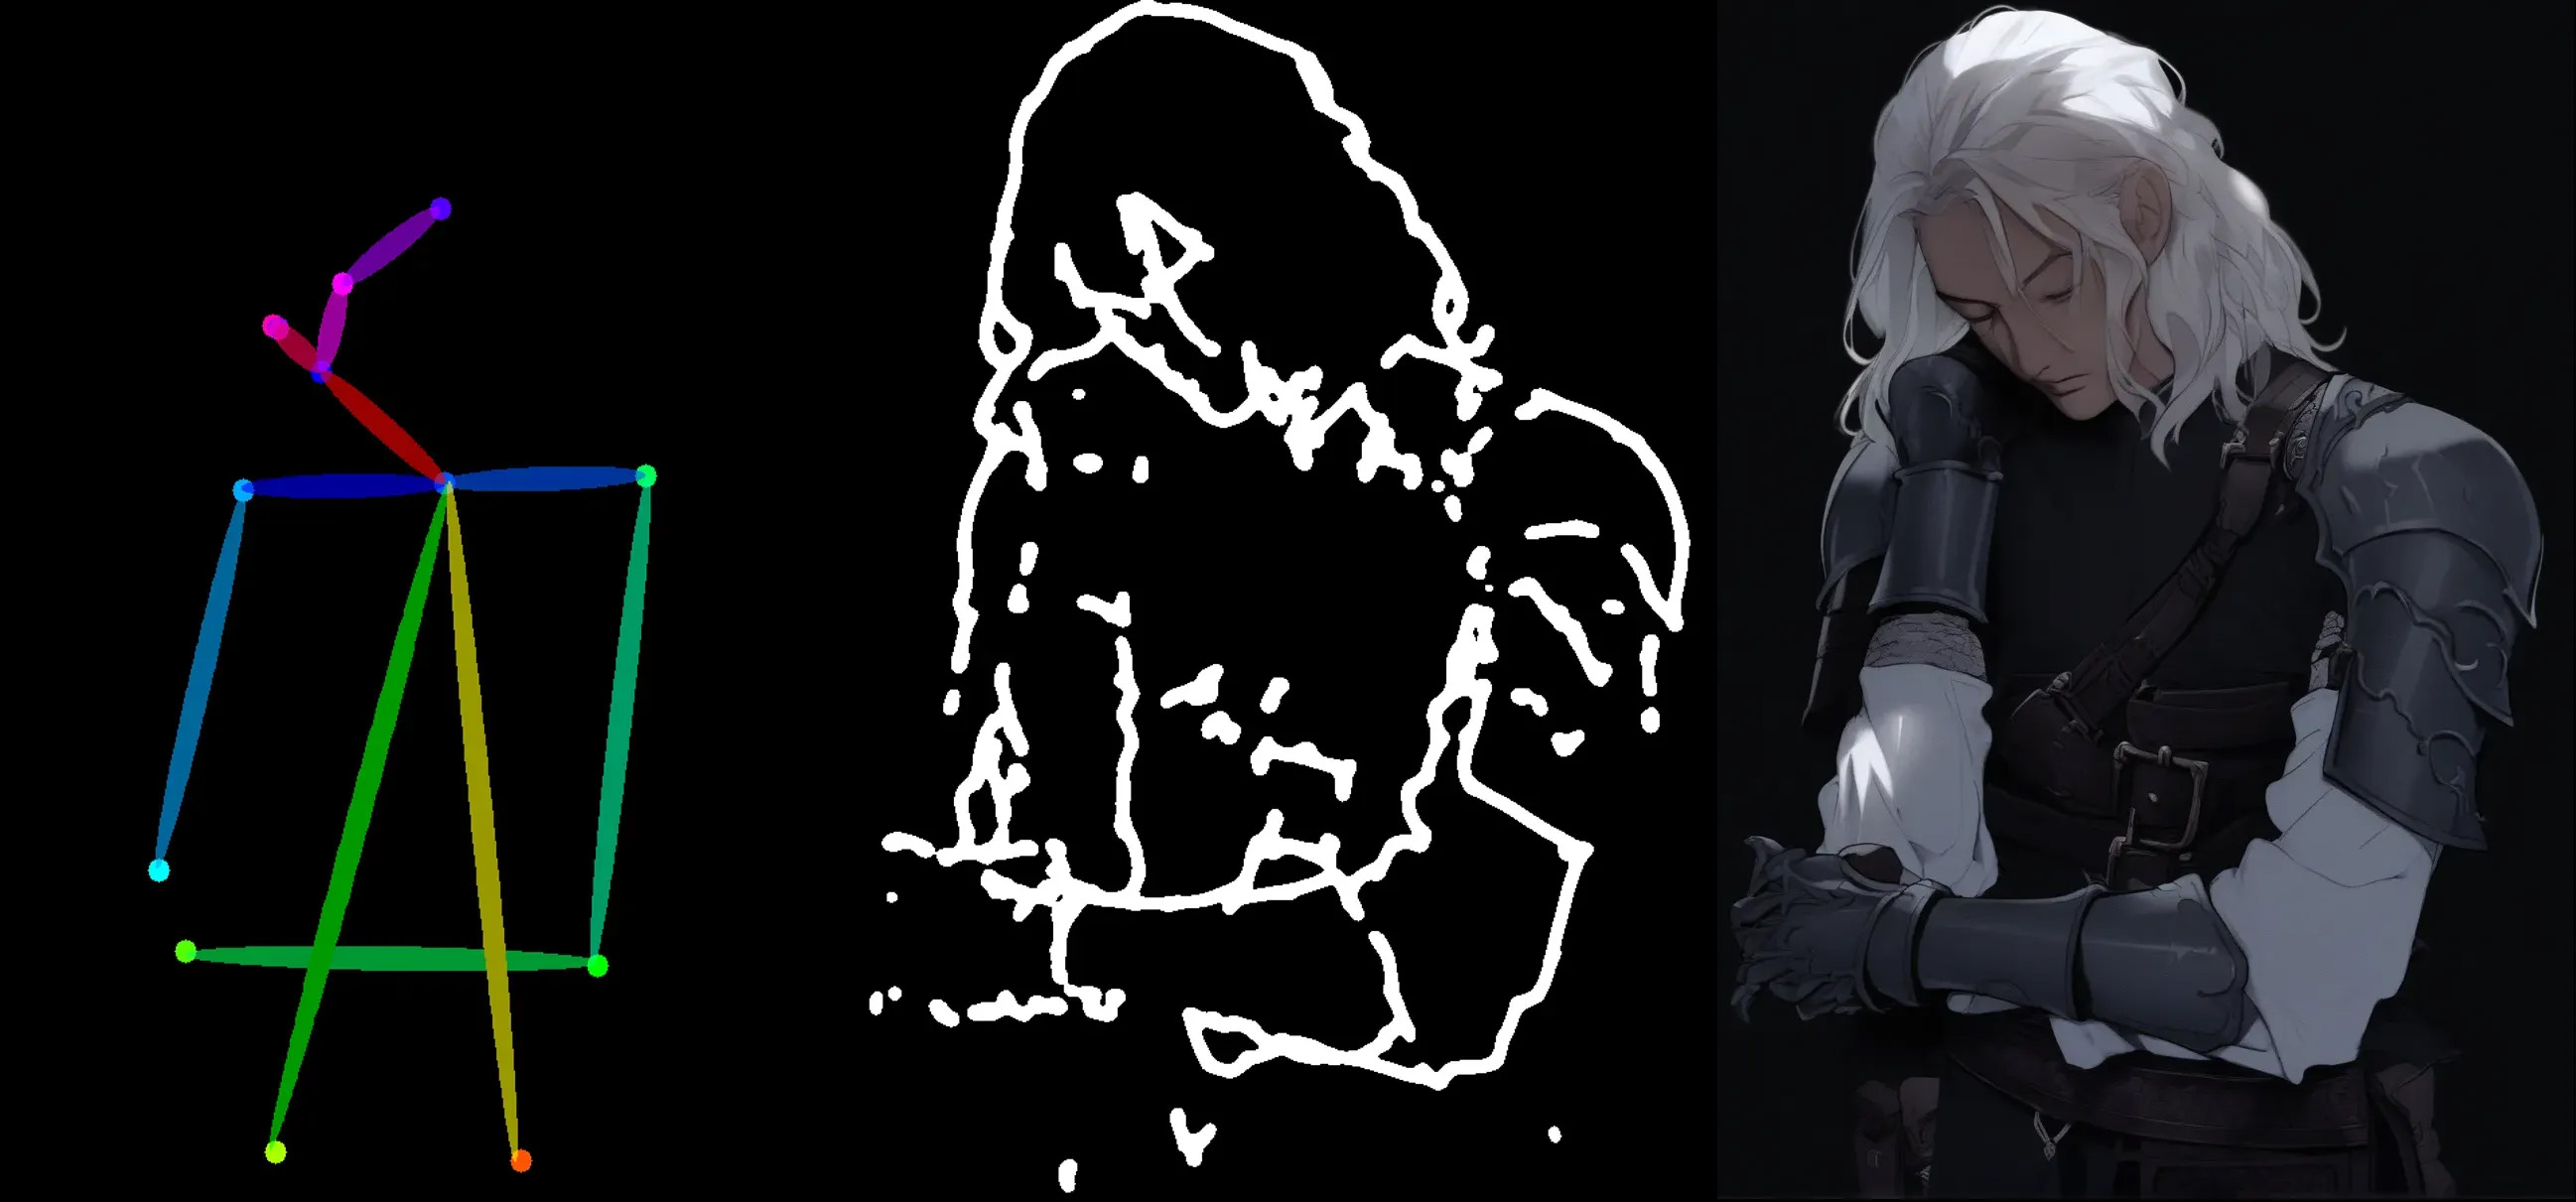 Image to Image
SDXL ControlNet Union Inpainting
An efficent SDXL multi-controlnet inpainting model.
 Text to Audio
Seed Audio 1.0
Seed Audio 1.0 is a new audio model from Bytedance that can generate high-quality, natural sounding audio using text, reference audios or an image.
 Text to Video
Seedance 1 Lite
A video generation model that offers text-to-video and image-to-video support for 5s or 10s videos, at 480p and 720p resolution
 Text to Video
Seedance 1 Pro
A pro version of Seedance that offers text-to-video and image-to-video support for 5s or 10s videos, at 480p and 1080p resolution
 Text to Image
Seedance 1 Pro Fast
A faster and cheaper version of Seedance 1 Pro
 Image to Video
Seedance 1.0 Pro Bytedance V1
Seedance 1.0 Pro, a high quality video generation model developed by Bytedance.
 Text to Video
Seedance 1.5 Pro
A joint audio-video model that accurately follows complex instructions.
 Image to Video
Seedance 2.0 Fast
ByteDance's most advanced text-to-video model, fast tier. Lower latency and cost with cinematic output, native audio, multi-shot editing, and director-level camera control.
 Image to Video
Seedance 2.0 Mini
Seedance 2.0 Mini is a faster version of Seedance 2.0 that brings great performance and high generation speed at a lower cost.
 Image to Video
Seedance 2.0 US
US hosted version of ByteDance's most advanced text-to-video model. Cinematic output with native audio, multi-shot editing, real-world physics, and director-level camera control.
 Video to Video
Seedance 2.5 Draft Complete
Draft completion endpoint for Seedance 2.5 - submit a draft id to regenerate the task at 1080p.
 Image to Video
Seedance 2.5 US Reference to Video
US-hosted ByteDance Seedance 2.5 generates video with native audio from up to 30 images, 10 videos, and 10 audio references. Supports reference-guided generation, video editing, and extension at 480p, 720p or 1080p.
 Text to Image
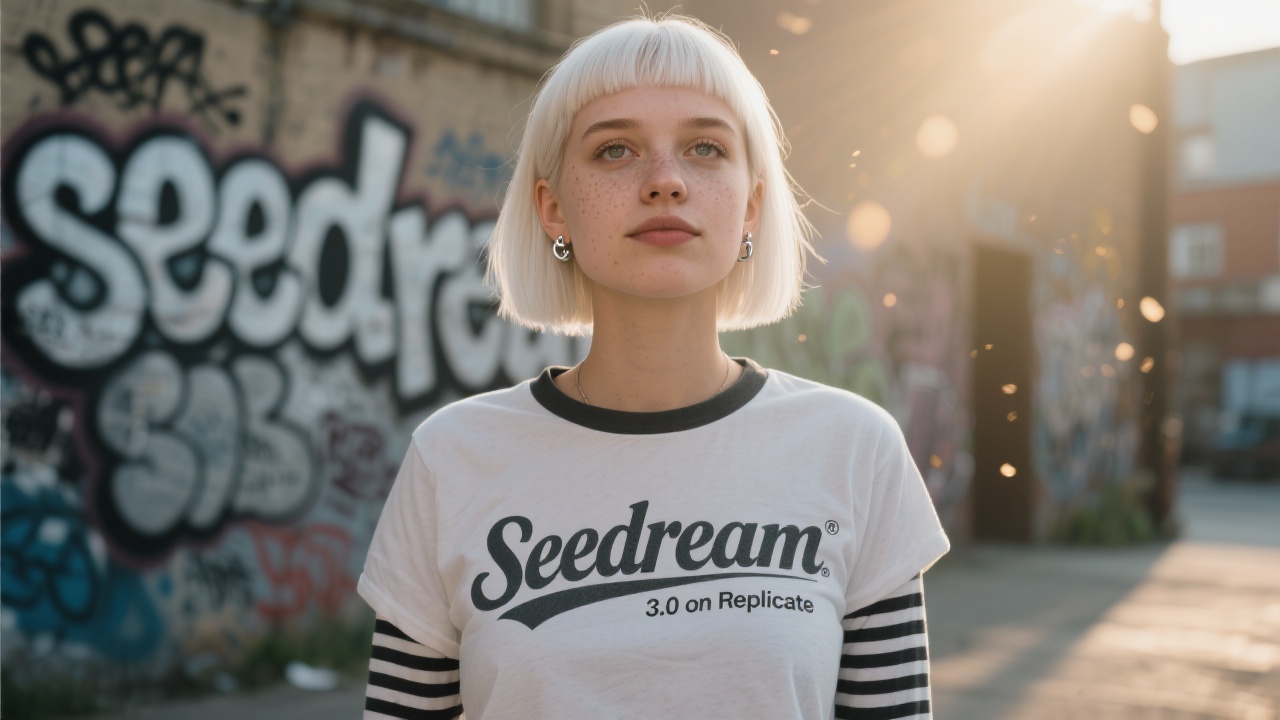
Seedream 3
A text-to-image model with support for native high-resolution (2K) image generation
 Text to Image
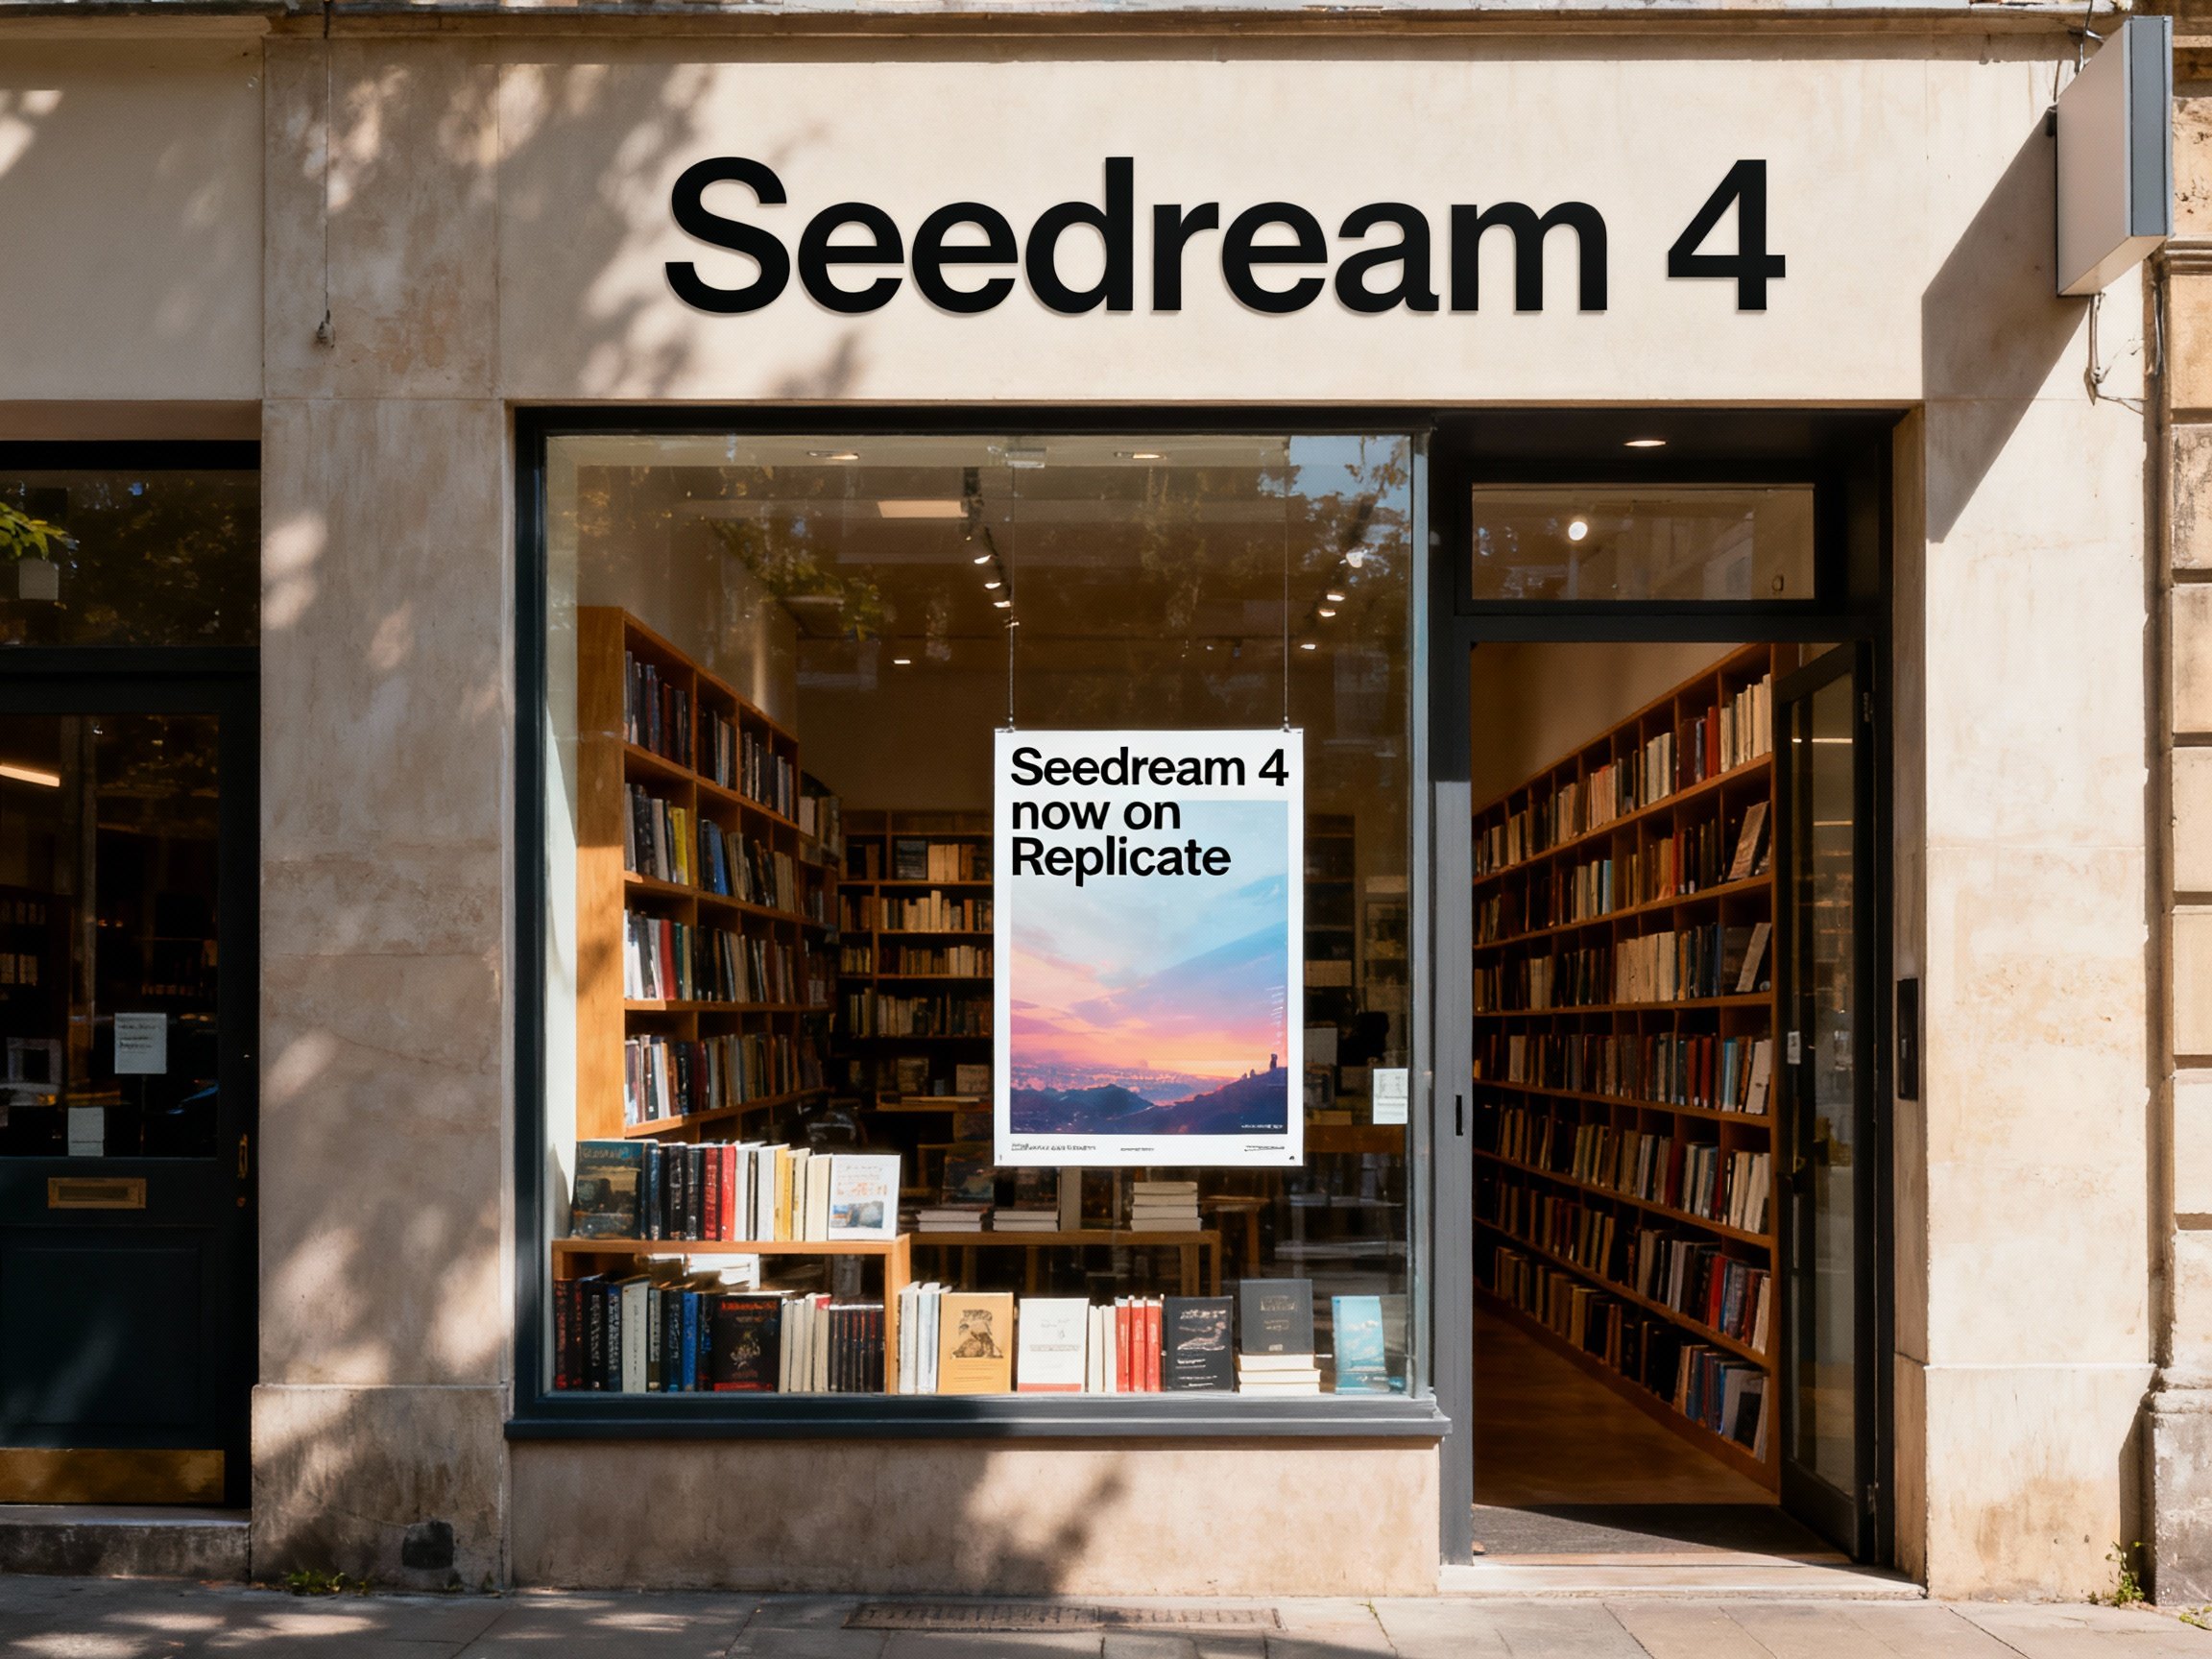
Seedream 4
Unified text-to-image generation and precise single-sentence editing at up to 4K resolution
 Text to Image
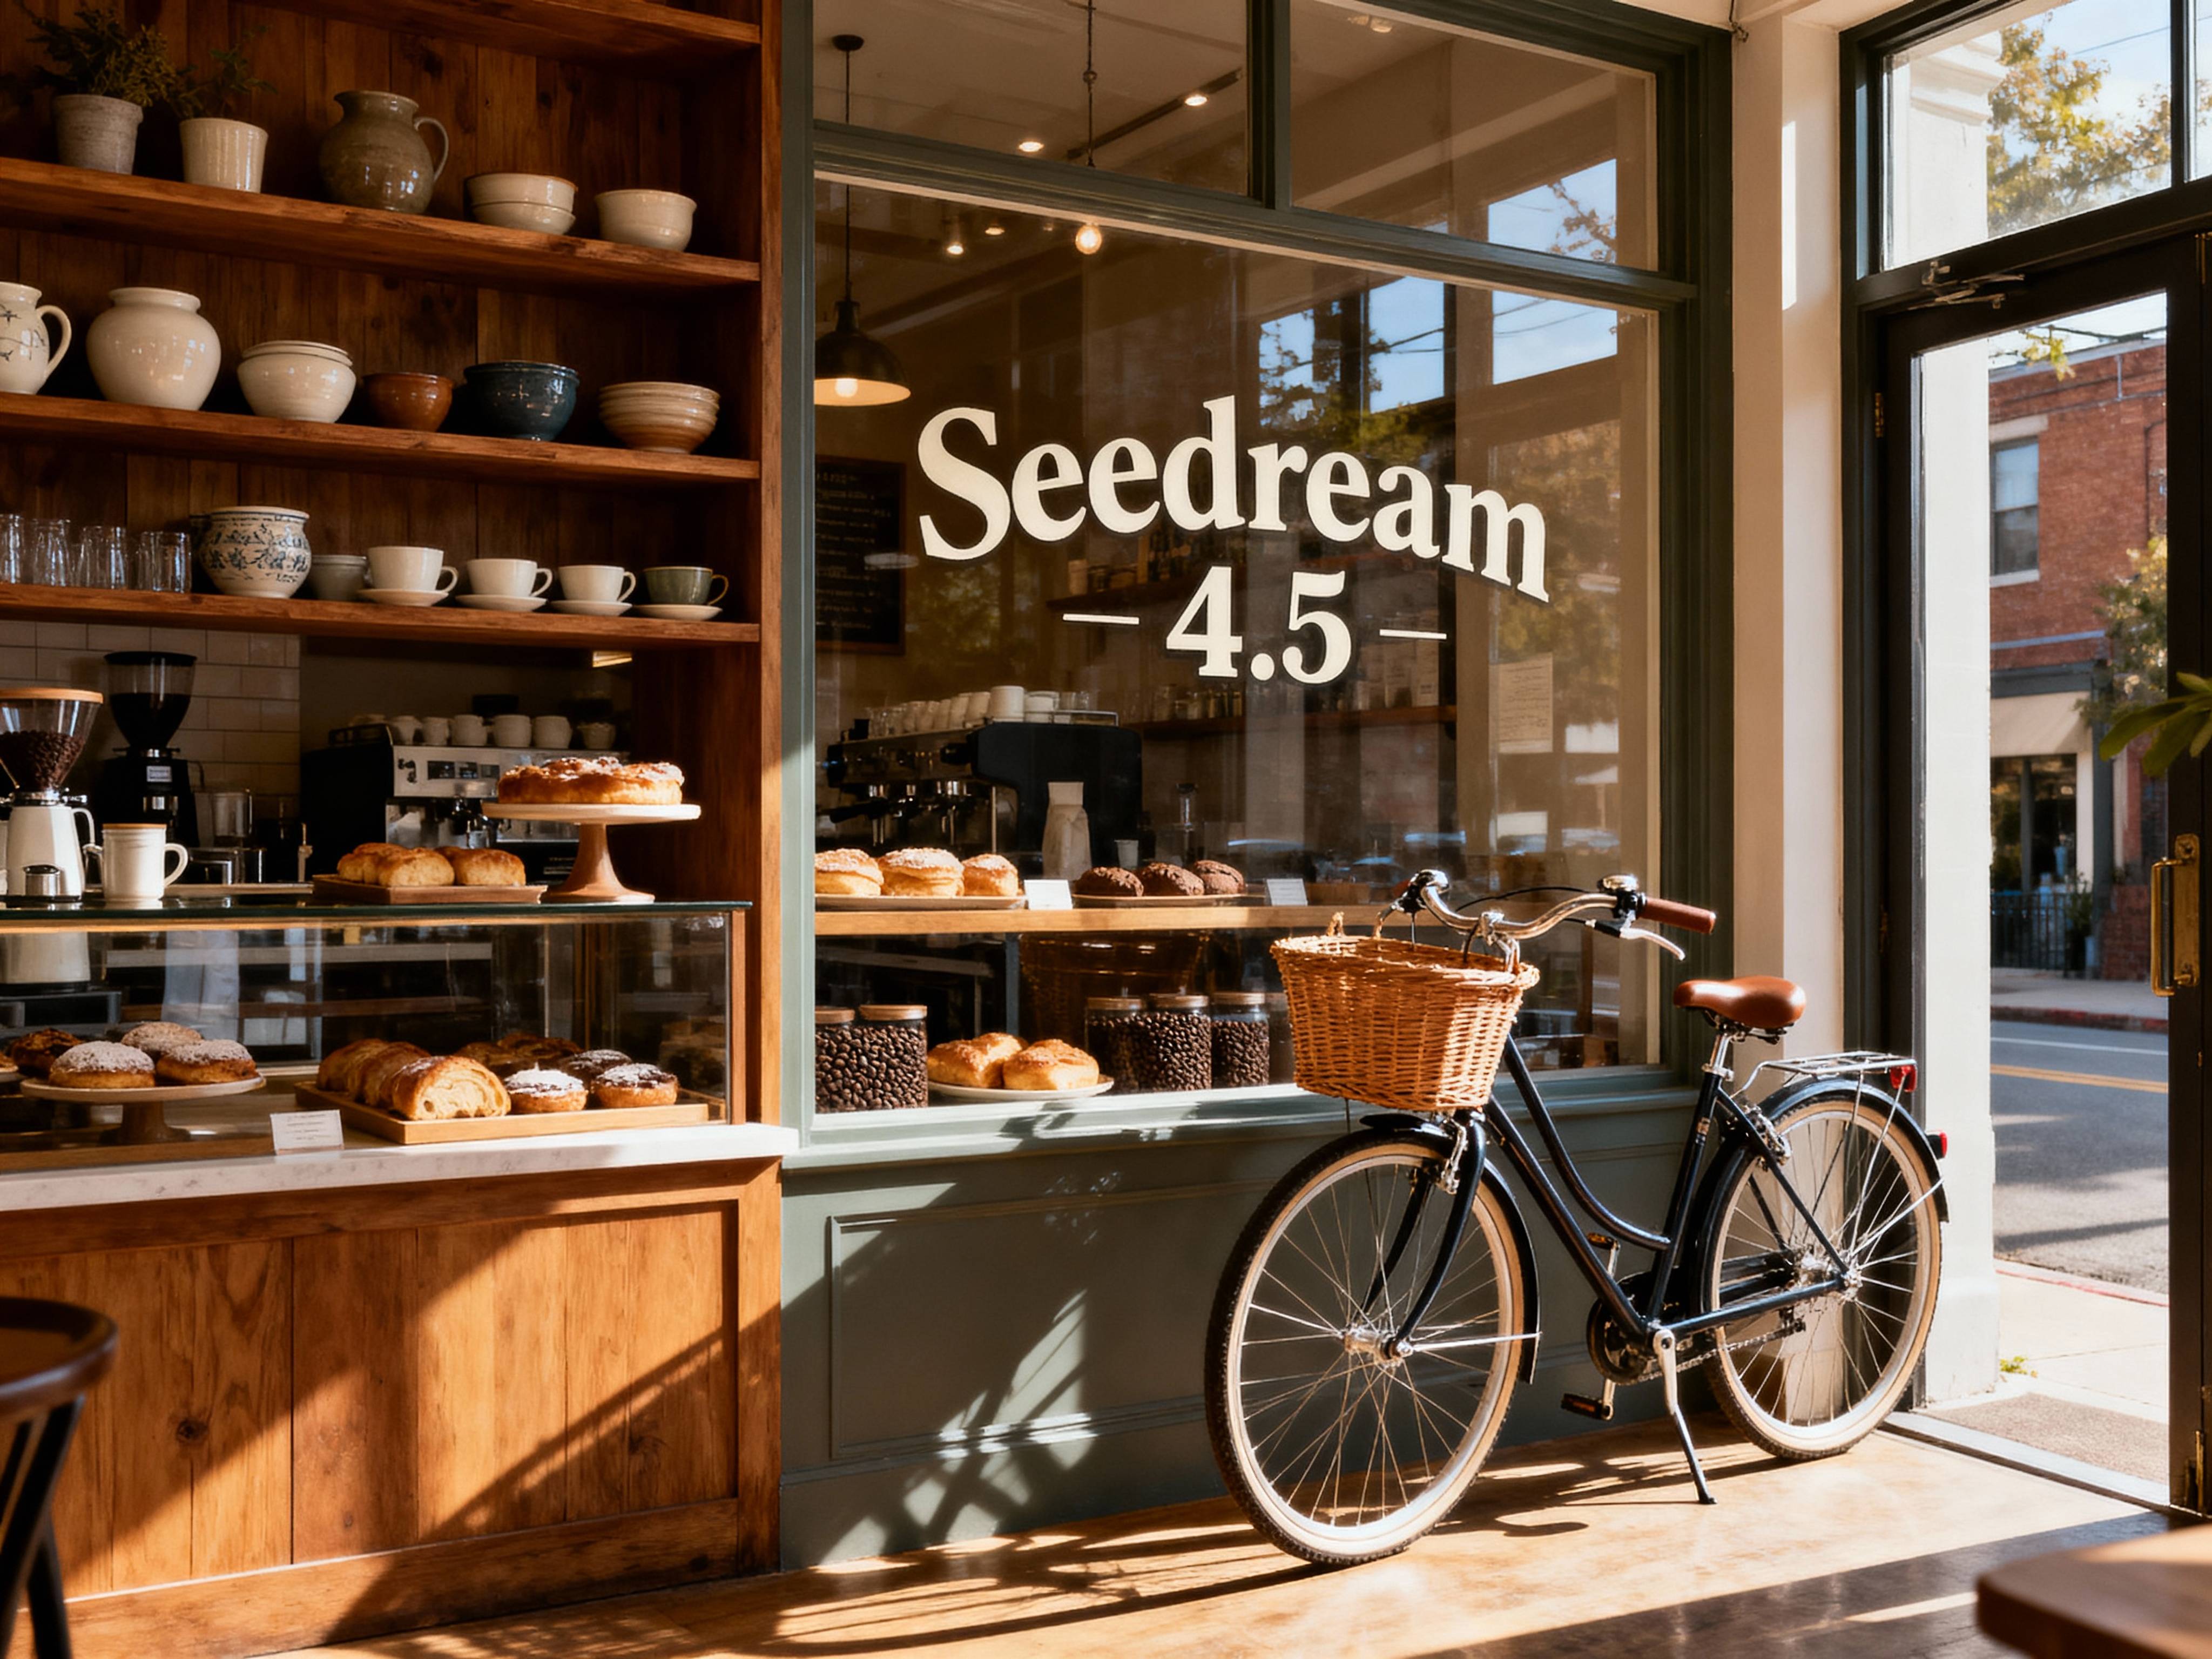
Seedream 4.5
Seedream 4.5: Upgraded Bytedance image model with stronger spatial understanding and world knowledge
 Text to Image
Seedream 5 Lite
Seedream 5.0 lite: image generation with built-in reasoning, example-based editing, and deep domain knowledge
 Text to Image
Seedream 5 Pro
ByteDance's flagship text-to-image and image editing model, generating sharp 1K and 2K images from text or up to 10 reference images
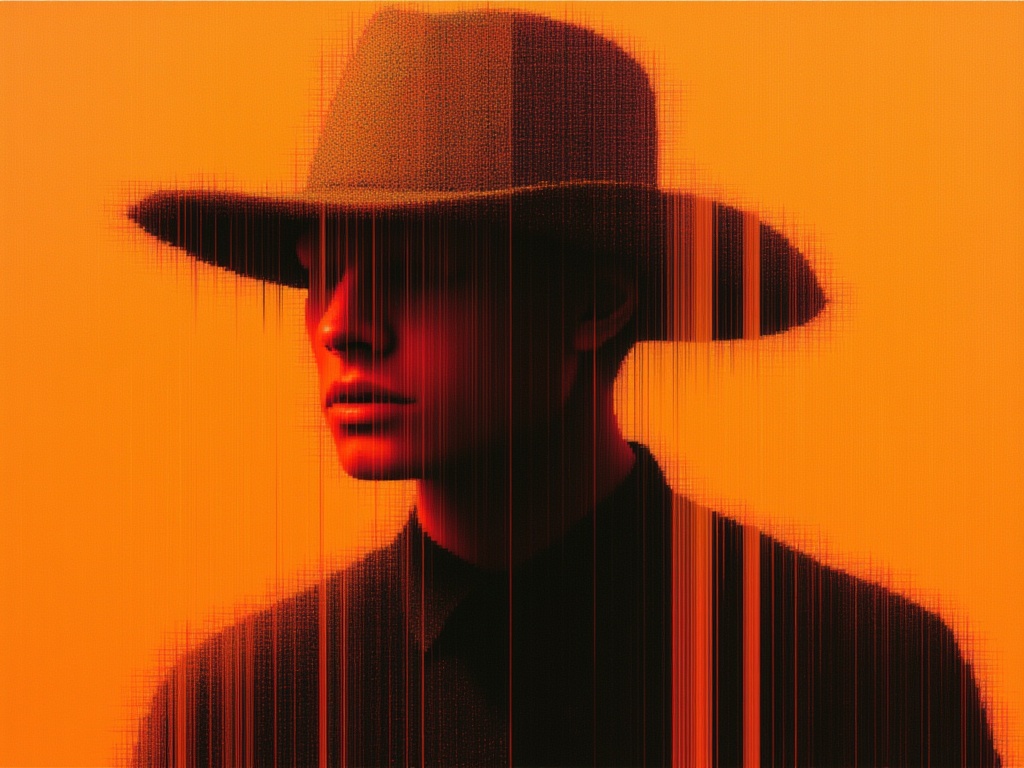 Image to Image
Seedream 5.0 Pro
Seedream 5.0 Pro is grounded, region-precise image editing model that changes one element while keeping the rest of the frame intact with layer separation, sketch completion, and up to 10 reference images.