Modeller
Görsel, video, metin ve ses üreten 1142 model. Ara, filtrele, hemen dene.
 Image to Image
Recraft Vectorize
Converts a given raster image to SVG format using Recraft model.
 Text to Image
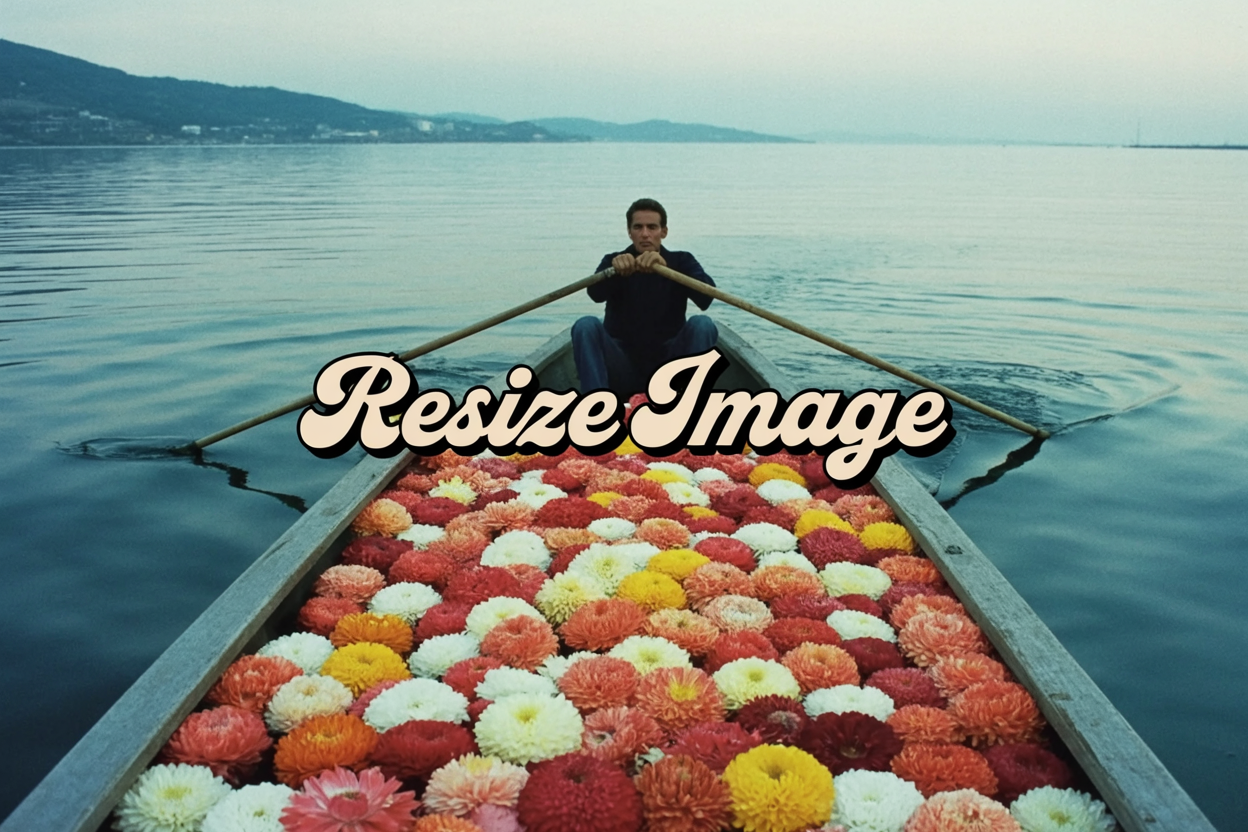
Reframe Image
Change the aspect ratio of any photo using AI (not cropping)
 Text to Video
Reframe Video
Change the aspect ratio of any video up to 30 seconds long, outputs will be 720p
 Image to Image
Relighting Image Apps V2
Adjust and enhance images with different lighting styles.
 Image to Image
Rembg Enhance (Remove Background Enhance)
Rembg-enhance is optimized for 2D vector images, 3D graphics, and photos by leveraging matting technology.
 Text to Image
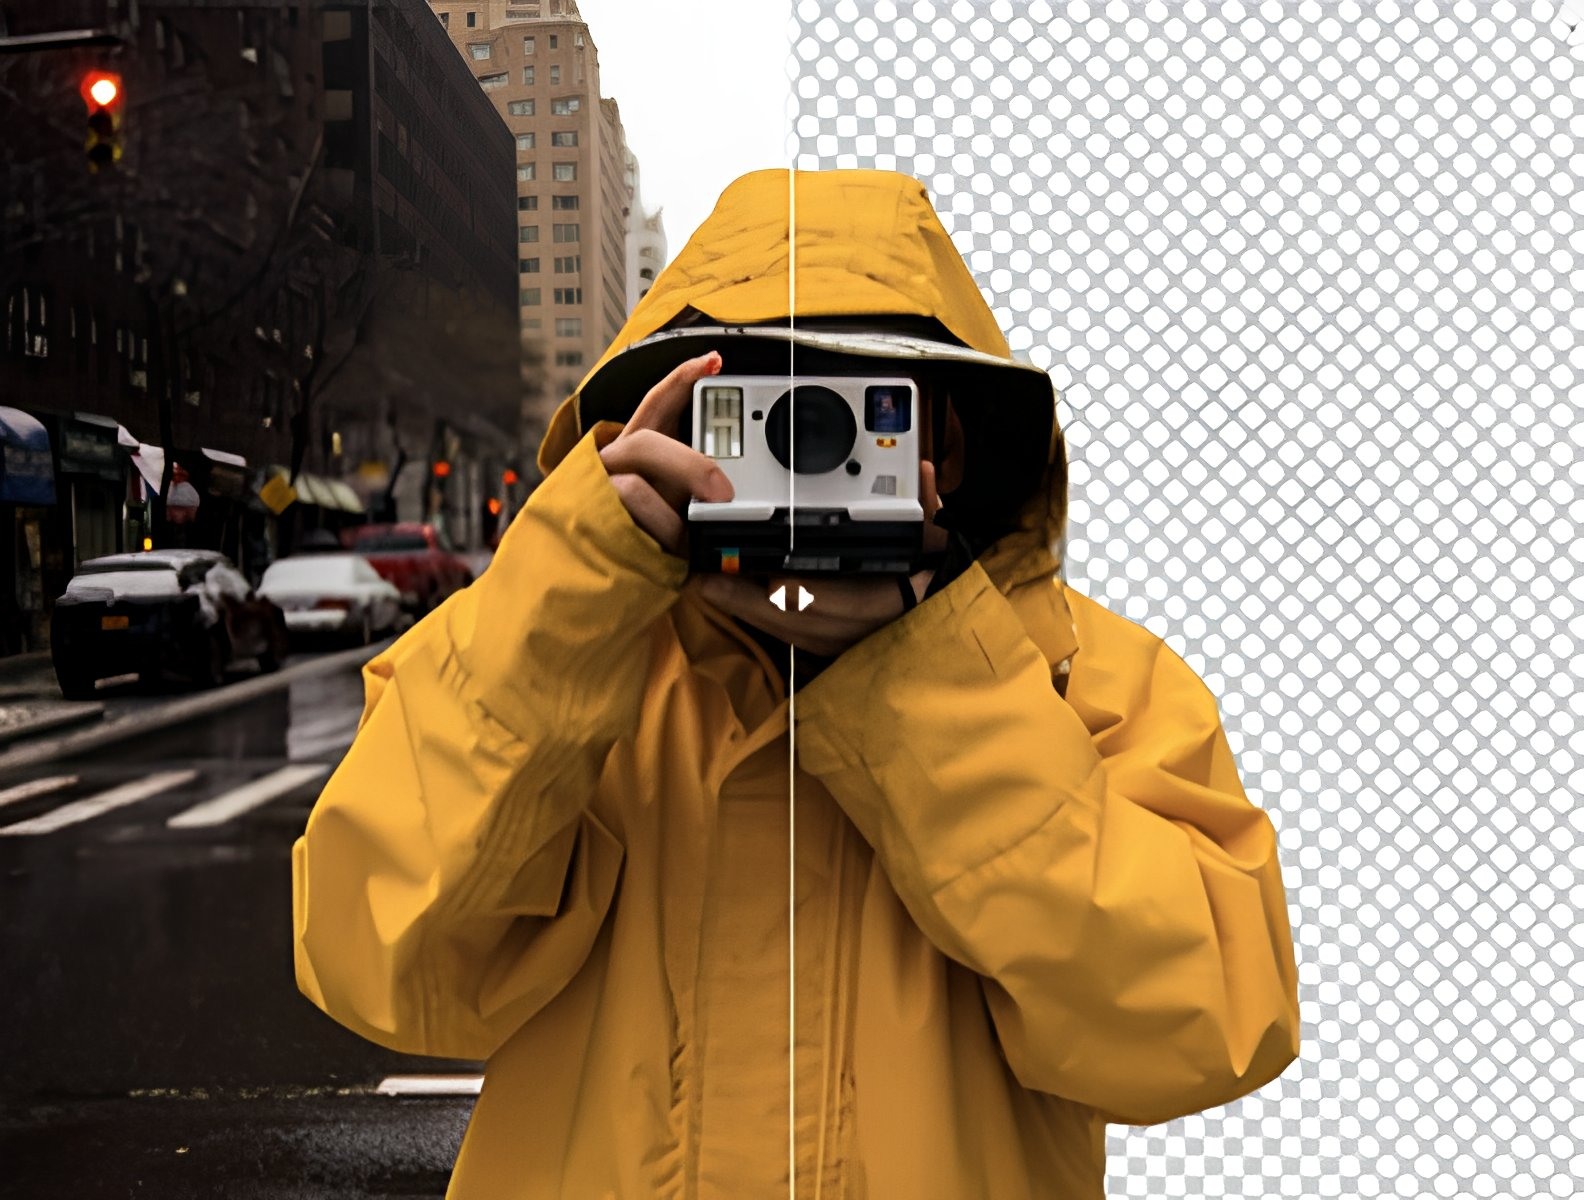
Remove Background
Bria AI's remove background model
 Image to Image
Remove Background Imageutils Rembg
Remove the background from an image.
 Image to Image
Replace Background
Generate professional, eCommerce-ready product shots by replacing backgrounds with realistic lighting and accurate perspective from a simple text prompt. Trained exclusively on licensed data for safe commercial use.
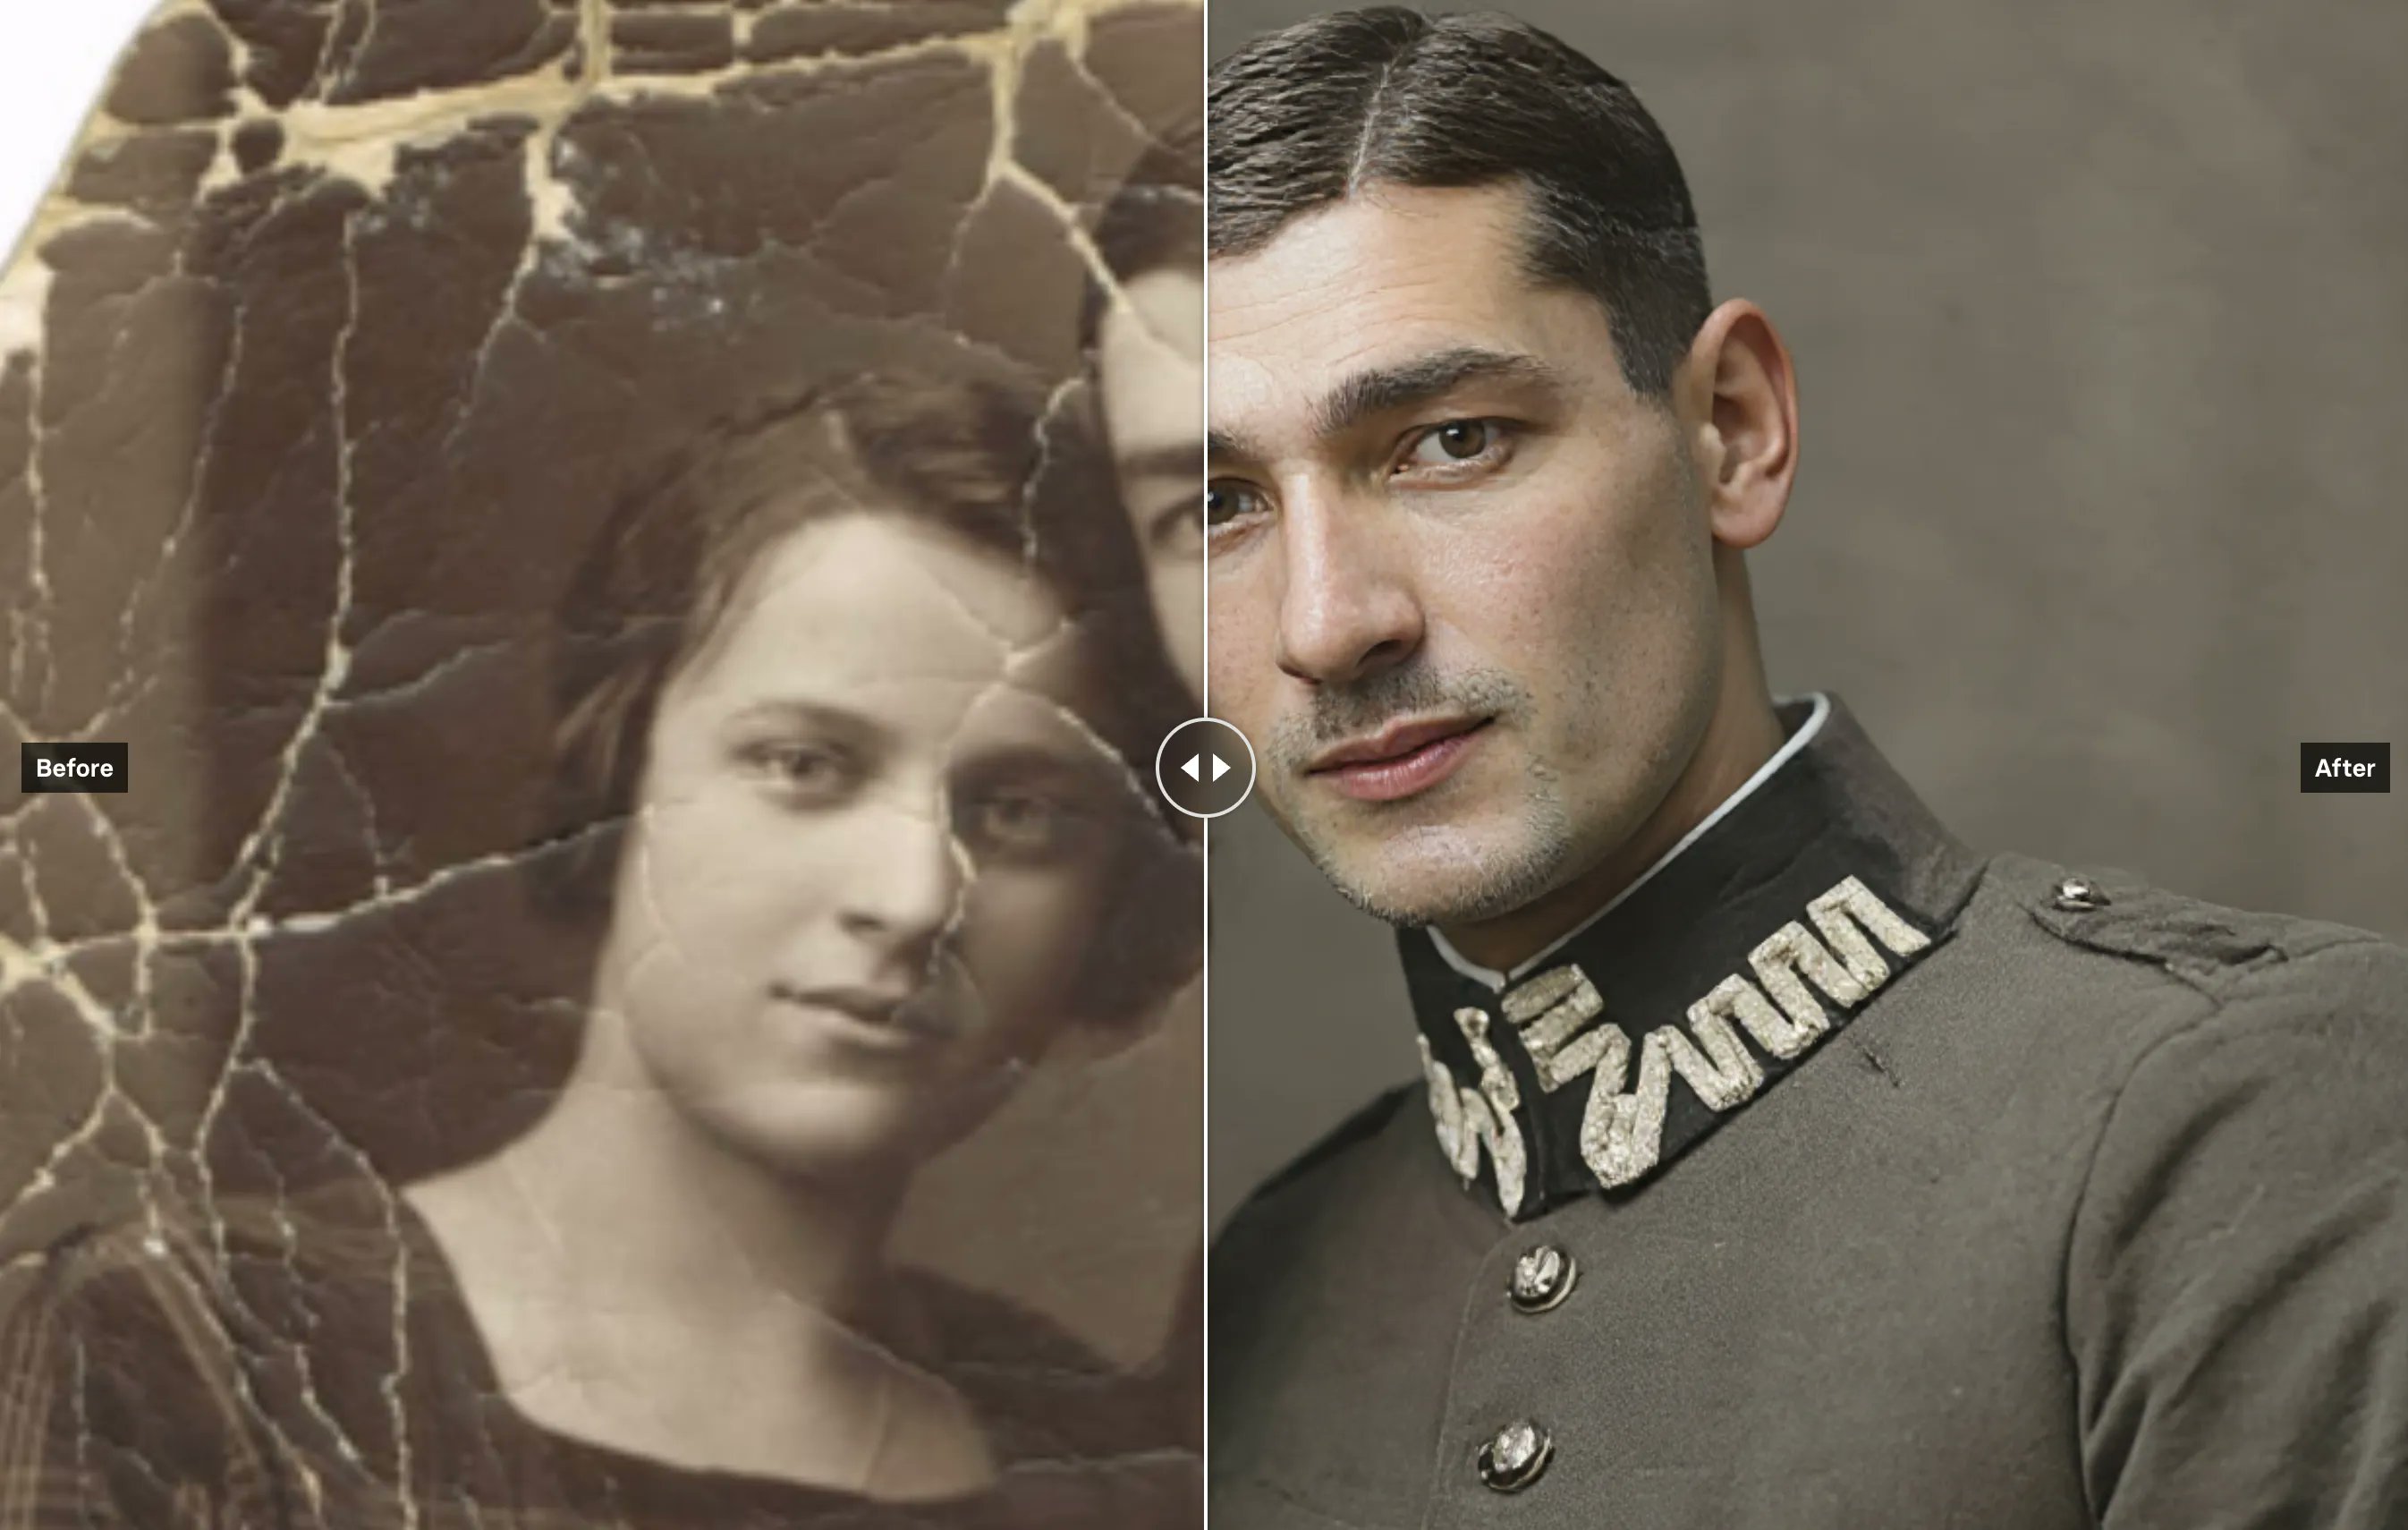 Image to Image
Restore Image
Use FLUX Kontext to restore, fix scratches and damage, and colorize old photos
 Text to Video
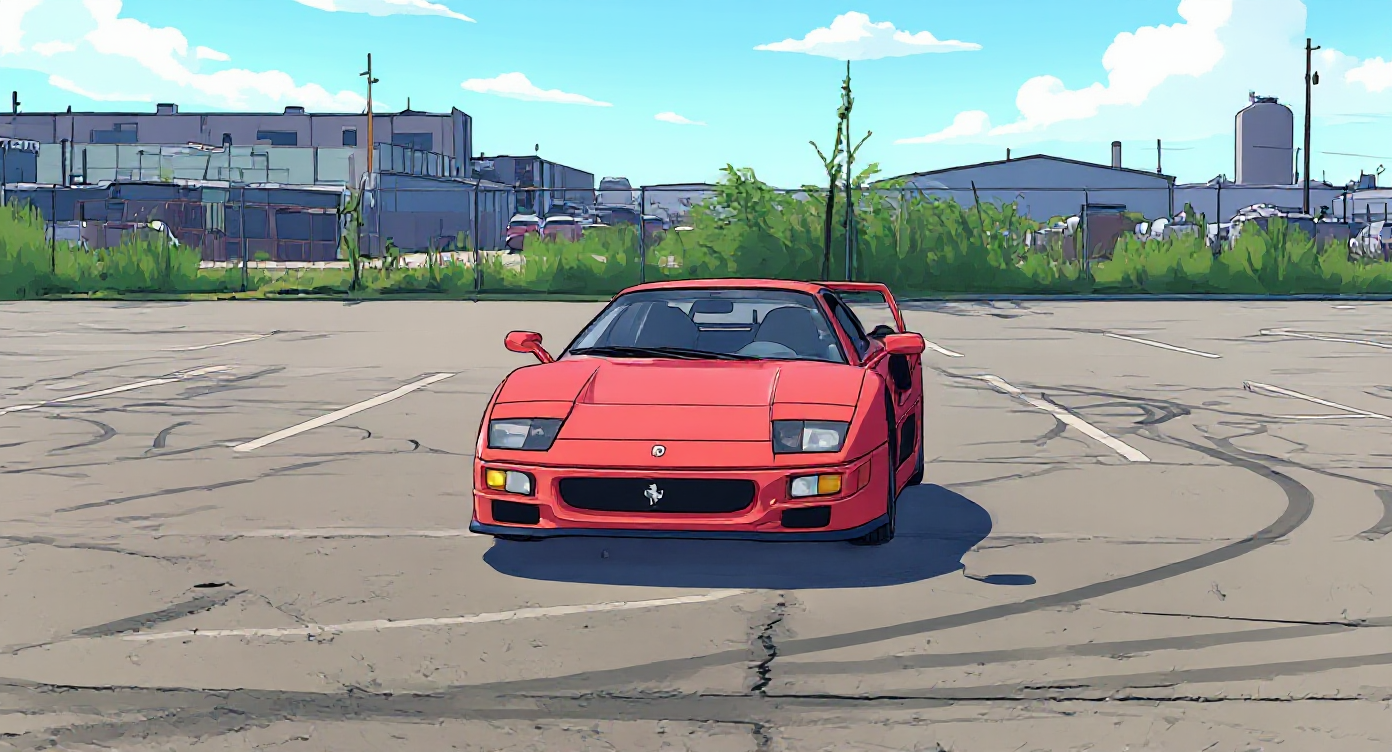
Restyle Video Frame
Use flux-kontext-pro to change the first or last frame of a video. Useful to use as inputs for restyling an entire video in a certain way
 Image to Image
RIFE
Interpolate images with RIFE - Real-Time Intermediate Flow Estimation
 Video to Video
RIFE Video
Interpolate videos with RIFE - Real-Time Intermediate Flow Estimation
 Text to Image
Rundiffusion Photo Flux
RunDiffusion Photo Flux provides insane realism. With this enhancer, textures and skin details burst to life, turning your favorite prompts into vivid, lifelike creations. Recommended to keep it at 0.65 to 0.80 weight. Supports resolutions up to 1536x1536.
 Image to Video
Sad Talker Sadtalker
Learning Realistic 3D Motion Coefficients for Stylized Audio-Driven Single Image Talking Face Animation
 Image to Image
Sam 3 1 Image
SAM 3.1 builds comes with Object Multiplex, a shared-memory approach for joint multi-object tracking that delivers faster speeds with larger number of objects tracked.
 Image to Image
Sam 3 1 Image Rle
SAM 3.1 builds comes with Object Multiplex, a shared-memory approach for joint multi-object tracking that delivers faster speeds with larger number of objects tracked.
 Video to Video
Sam 3 1 Video
SAM 3.1 builds comes with Object Multiplex, a shared-memory approach for joint multi-object tracking that delivers faster speeds with larger number of objects tracked.
 Video to Video
Sam 3 1 Video Rle
SAM 3.1 builds comes with Object Multiplex, a shared-memory approach for joint multi-object tracking that delivers faster speeds with larger number of objects tracked.
 3D to 3D
Sam 3 3D Align
SAM 3D enables full scene reconstructions, placing objects and humans in a shared context together.
 Image to 3D
Sam 3 3D Body
SAM 3D allows for accurate 3D reconstruction of human body shape and position from a single image.
 Image to 3D
Sam 3 3D Objects
SAM 3D enables precise 3D reconstruction of objects from real images, while accurately reconstructing their geometry and texture.
 Video to Video
Sam 3 Video
SAM 3 is a unified foundation model for promptable segmentation in images and videos. It can detect, segment, and track objects using text or visual prompts such as points, boxes, and masks.
 Video to Video
Sam 3 Video Rle
SAM 3 is a unified foundation model for promptable segmentation in images and videos. It can detect, segment, and track objects using text or visual prompts such as points, boxes, and masks.
 Text to Image
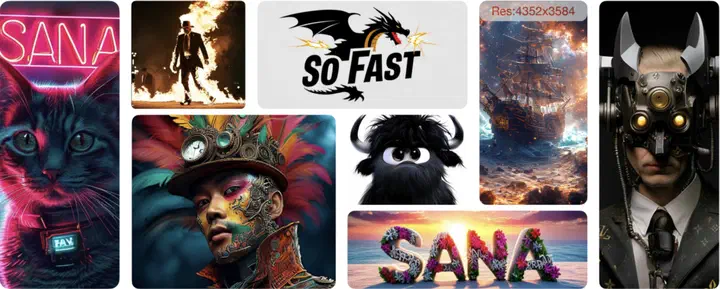
Sana
Sana can synthesize high-resolution, high-quality images with strong text-image alignment at a remarkably fast speed, with the ability to generate 4K images in less than a second.