Modeller
Görsel, video, metin ve ses üreten 1142 model. Ara, filtrele, hemen dene.
 Image to Image
ControlLight Control Light
ControlLight is a LoRA fine-tune of FLUX.2 [klein] 9B that enhances low-light images while preserving scene structure and fine details, with a single alpha parameter that gives continuous control over enhancement strength from subtle to full brightening.
 Image to Image
ControlNet SDXL Fast Canny Inpainting
Generate Images with ControlNet.
 Image to Video
Cosmos 3 Super
Cosmos3 is a collection of Omnimodal world models capable of generating dynamic, high-quality video, image, audio, and action commands from combinations of text, image, video, and action trajectory inputs.
 Image to Video
Cosmos Predict 2.5 2B
Generate video from text and videos using NVIDIA's 2B Cosmos Post-Trained Model
 Text to Video
Cosmos Predict 2.5 2B Distilled
Generate video from text and videos using NVIDIA's 2B Cosmos Distilled Model
 Text to 3D
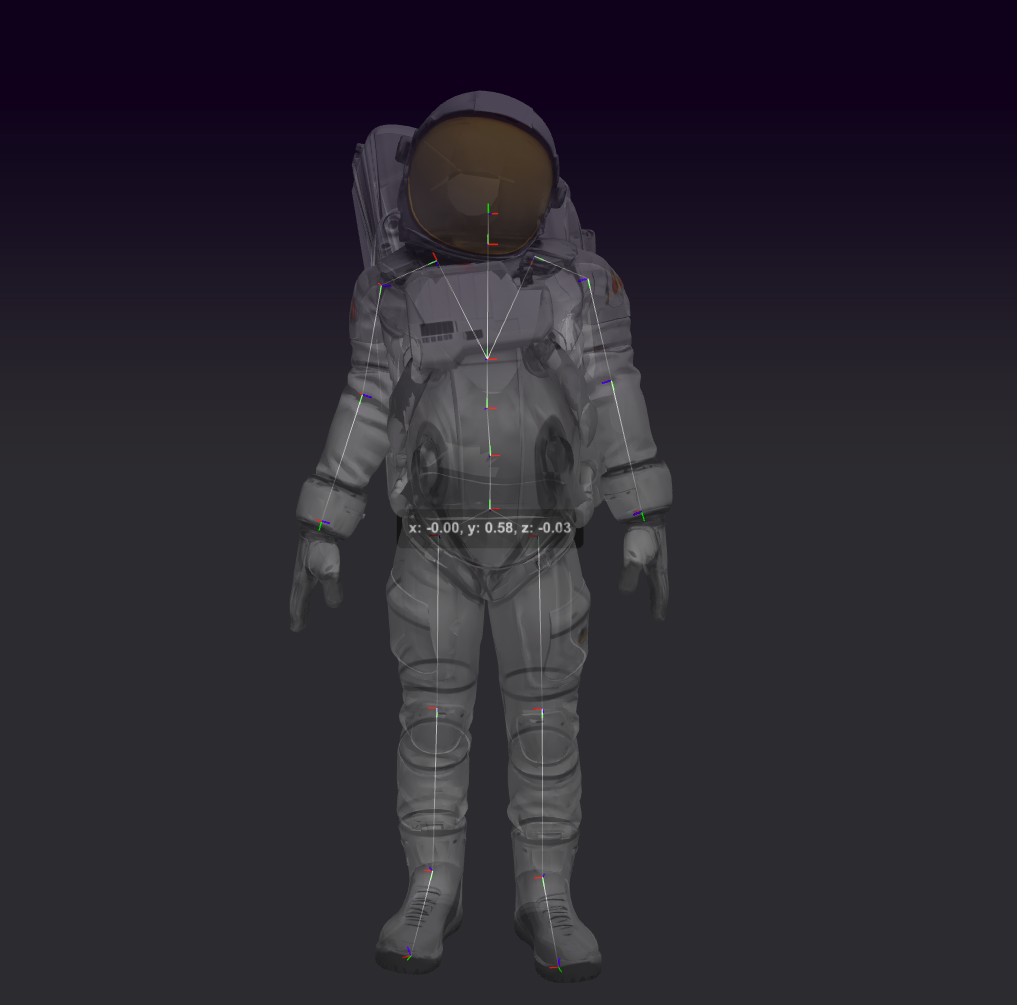
Create Character V1
Rig any 3D bipedal character mesh
 Image to Video
Creatify Aurora
Generate high fidelity, studio quality videos of your avatar speaking or singing using the Aurora from Creatify team!
 Image to Image
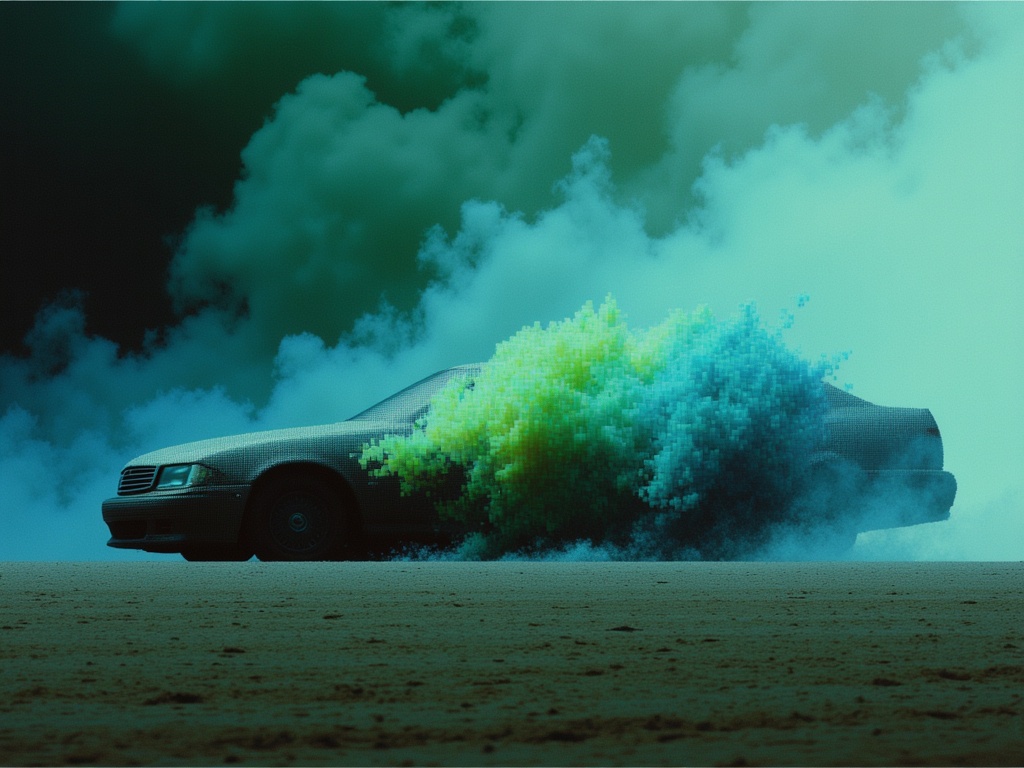
Crystal Upscaler
An advanced image enhancement tool designed specifically for facial details and portrait photography, utilizing Clarity AI's upscaling technology.
 Video to Video
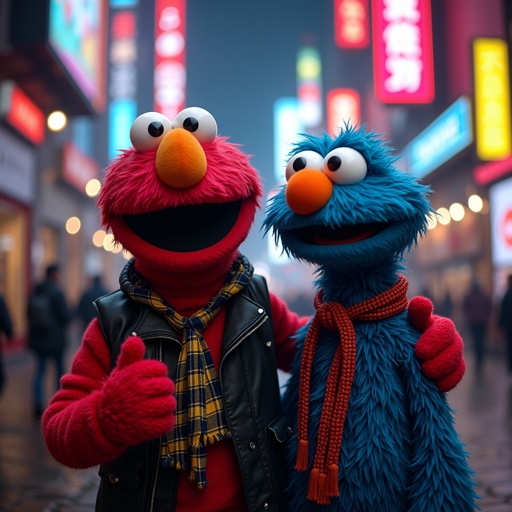
Crystal Upscaler [Video]
Do high precision video upscaling that respects the original video perfectly using Crystal Upscaler's new video upscaling method!
 Text to Audio
CSM 1B
CSM (Conversational Speech Model) is a speech generation model from Sesame that generates RVQ audio codes from text and audio inputs.
 Text to Image
Dall E 2
The original classic DALLᐧE 2
 Text to Image
Dall E 3
An AI system that can create realistic images and art from a description in natural language.
 Image to Video
Davinci Magihuman
Expressive facial performance, natural speech-expression coordination, realistic body motion, and accurate audio-video synchronization with DaVinci-MagiHuman model
 Image to Image
DDColor
Bring colors into old or new black and white photos with DDColor.
 Audio to Audio
DeepFilterNet 3 Deepfilternet3
Enhance speech audio by removing background noise and upsampling to 48KHz
 Text to Image
DeepSeek Janus-Pro
DeepSeek Janus-Pro is a novel text-to-image model that unifies multimodal understanding and generation through an autoregressive framework
 Audio to Audio
Demucs
SOTA stemming model for voice, drums, bass, guitar and more.
 Video to Video
Depth Anything Video
Generates depth maps from video using Video Depth Anything (CVPR 2025). Produces per-frame depth estimation with temporal consistency across frames. Supports 3 model sizes (Small, Base, Large), 5 colormaps including grayscale, side-by-side comparison with the original video, and raw depth export as .npz. Useful for 3D reconstruction, video effects, compositing, and scene understanding.
 Image to Image
Depth Of Field
Bring your subjects into focus with FLUX.1 Kontext [pro]
 Text to Speech
Dia TTS
Dia directly generates realistic dialogue from transcripts. Audio conditioning enables emotion control. Produces natural nonverbals like laughter and throat clearing.
 Audio to Audio
Dia Tts Voice Clone
Clone dialog voices from a sample audio and generate dialogs from text prompts using the Dia TTS which leverages advanced AI techniques to create high-quality text-to-speech.
 Text to Audio
DiffRhythm
DiffRhythm is a blazing fast model for transforming lyrics into full songs. It boasts the capability to generate full songs in less than 30 seconds.
 Image to Image
DocRes
Enhance low-resolution, blur, shadowed documents with the superior quality of docres for sharper, clearer results.
 Image to Image
DocRes Dewarp
Enhance wraped, folded documents with the superior quality of docres for sharper, clearer results.