Modeller
Görsel, video, metin ve ses üreten 1142 model. Ara, filtrele, hemen dene.
 Image to Image
FLUX1.1 [pro] ultra Flux V1.1
FLUX1.1 [pro] ultra is the newest version of FLUX1.1 [pro], maintaining professional-grade image quality while delivering up to 2K resolution with improved photo realism.
 Image to Video
Framepack
Framepack is an efficient Image-to-video model that autoregressively generates videos.
 Image to Video
Framepack F1
Framepack is an efficient Image-to-video model that autoregressively generates videos.
 Image to Video
Framepack Flf2v
Framepack is an efficient Image-to-video model that autoregressively generates videos.
 Image to Image
Gemini 2.5 Flash Image
Google's famous original image generation and editing model, a.k.a Nano Banana
 Image to Image
Gemini 3 Pro Image Preview
Gemini 3 Pro Image (a.k.a Nano Banana Pro) is Google's state-of-the-art high-fidelity image generation and editing model
 Image to Image
Gemini 3.1 Flash Image Preview
Gemini 3.1 Flash Image (a.k.a. Nano Banana 2) is Google's new state-of-the-art fast image generation and editing model
 Text to Speech
Gemini 3.1 Flash Tts
Newest audio model from Google introduces granular audio tags that give you precise control to direct AI speech for expressive audio generation.
 Text to Speech
Gemini 3.8 Flash Lite TTS
Generate expressive speech with Gemini 3.8 Flash Lite TTS. Choose from 30 voices, guide delivery with style instructions, and create single-speaker narration or two-speaker dialogue.
 Text to Speech
Gemini 3.8 Flash TTS
Generate expressive speech with Gemini 3.8 Flash TTS. Choose from 30 voices, direct delivery with style instructions, and create single-speaker narration or two-speaker dialogue.
 Text to Video
Gemini Omni 1.1
Google's fast multimodal video generation and editing model with native audio, using the Interactions API
 Image to Video
Gemini Omni Flash
Generates video with audio from combined multimodal references. Accepts text, images, audio, and video together as input to guide subject, motion, style, and sound in the output.
 Image to Video
Gemini Omni Flash 1.1 V1.1
Gemini Omni Flash 1.1 is Google's multimodal video model. This endpoint edits video through natural-language instruction, applying the requested change while preserving the parts of the scene you want kept, and carrying character and scene consistency across successive edits.
 Text to Audio
Gemini TTS
Use Gemini TTS Models to convert your prompts to real audio.
 Text to Video
Gen 4.5
State-of-the-art video motion quality, prompt adherence and visual fidelity
 Text to Video
Gen4 Aleph
A new way to edit, transform and generate video
 Text to Image
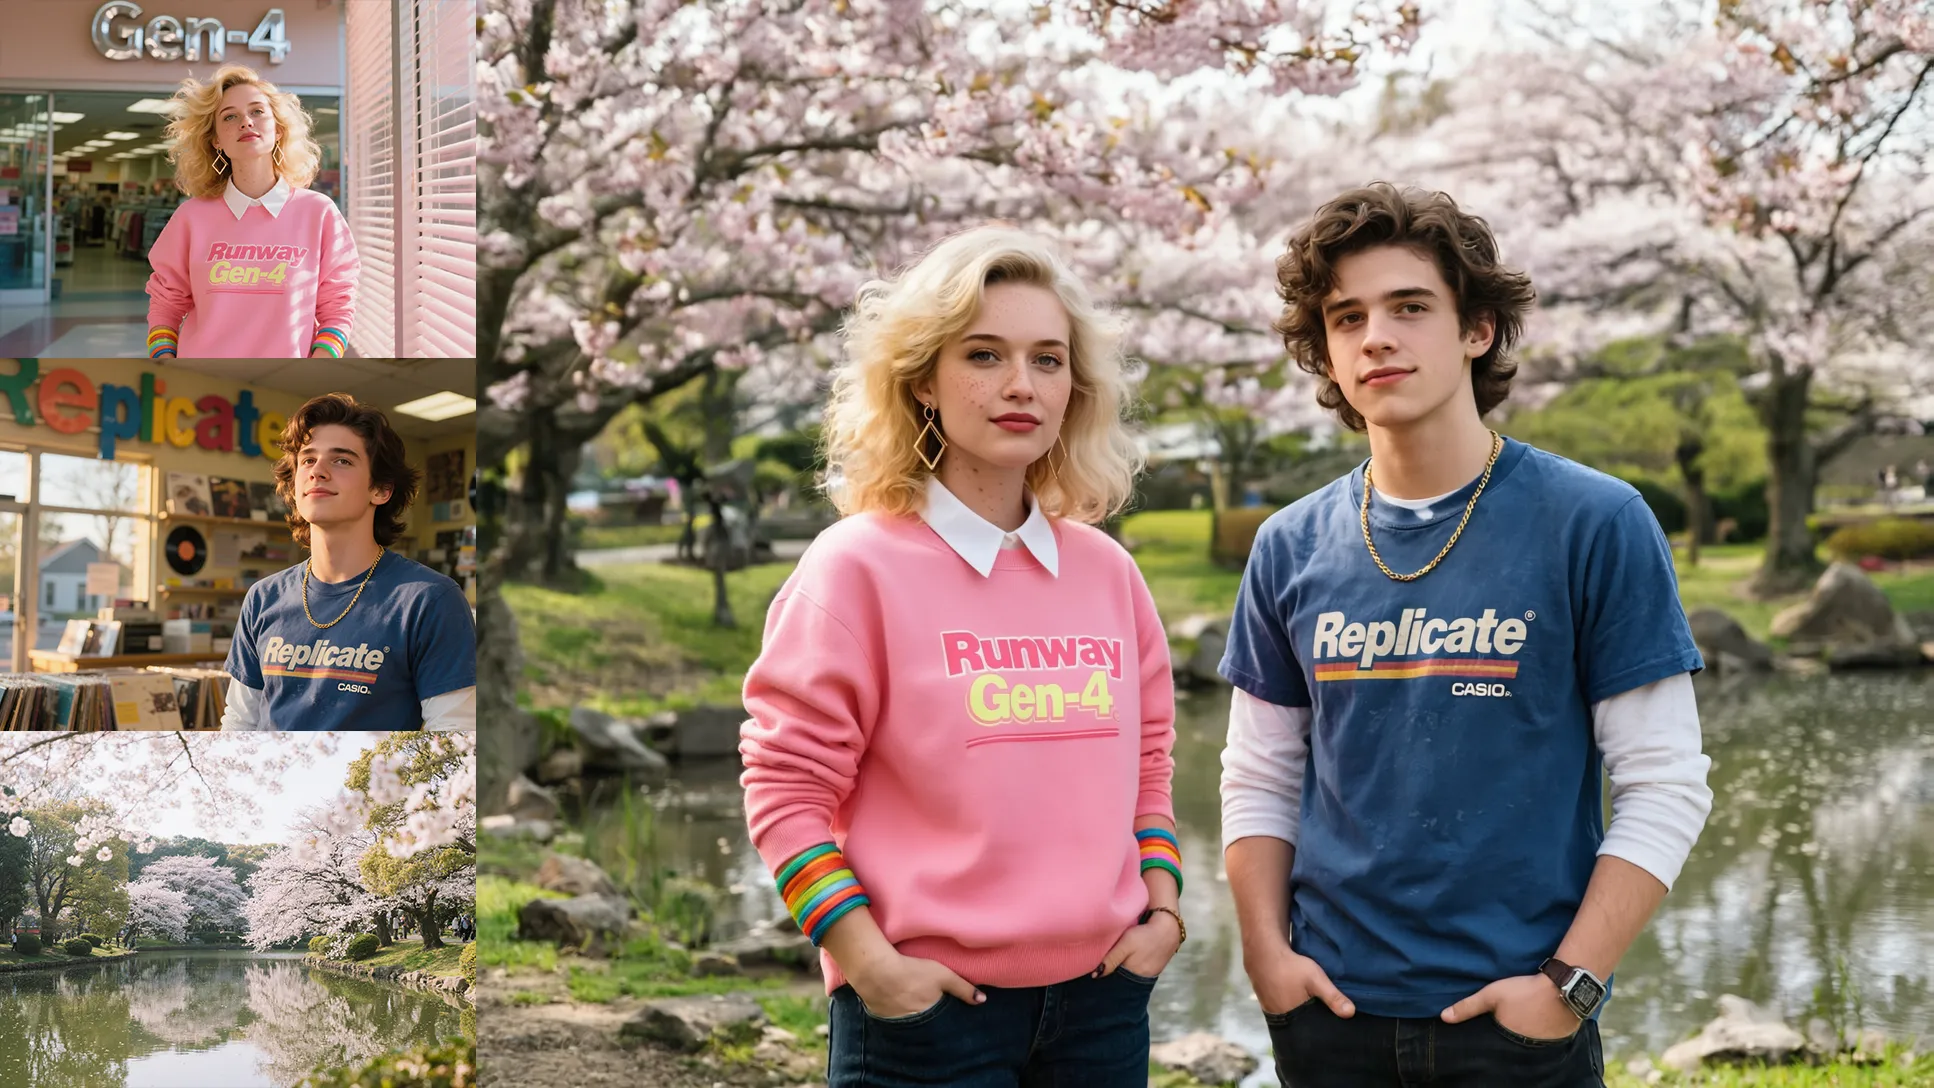
Gen4 Image
Runway's Gen-4 Image model with references. Use up to 3 reference images to create the exact image you need. Capture every angle.
 Text to Image
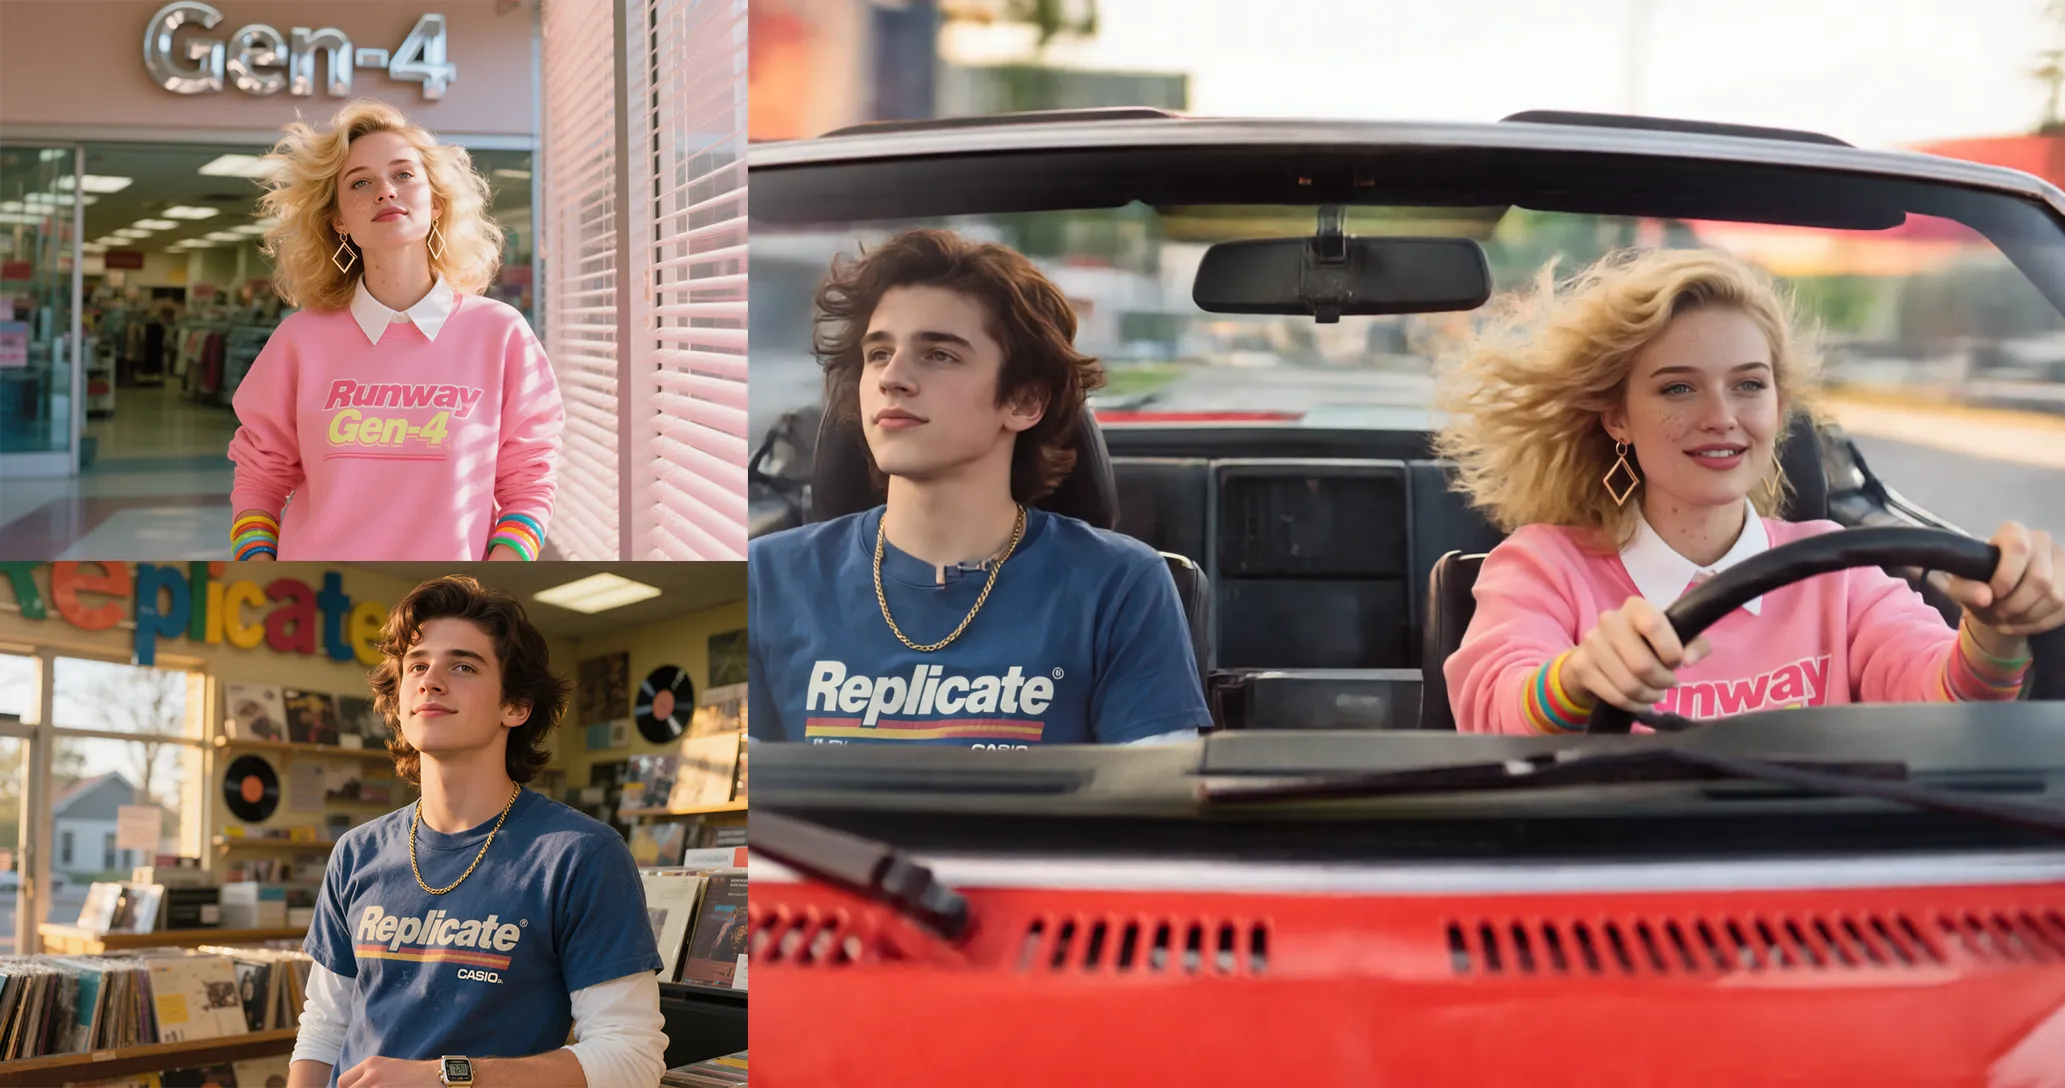
Gen4 Image Turbo
Gen-4 Image Turbo is cheaper and 2.5x faster than Gen-4 Image. An image model with references, use up to 3 reference images to create the exact image you need. Capture every angle.
 Image to Video
Gen4 Turbo
Generate 5s and 10s 720p videos fast
 Text to Image
Generate Background
Bria Background Generation allows for efficient swapping of backgrounds in images via text prompts or reference image, delivering realistic and polished results. Trained exclusively on licensed data for safe and risk-free commercial use
 Image to Image
Genfill V2
The GenFill Route enables the generation of objects by prompt in a specific region of an image. You can define the area for object generation by using a mask that outlines the region where the object will be created. Our model is optimized to work seamlessly with blob-shaped masks.
 Image to Image
Ghiblify Images
Reimagine and transform your ordinary photos into enchanting Studio Ghibli style artwork
 Image to Image
Glm Image
Create high-quality images with accurate text rendering and rich knowledge details—supports editing, style transfer, and maintaining consistent characters across multiple images.
 Image to Image
Google Virtual Try On
Generate realistic virtual try-on images from a person image and a clothing product image.